GEO (generative engine optimization) measurement shows how often AI models recommend a brand across identical, repeated prompts and model platforms and identifies the sources models cite when they do.
GEO and AEO improve a brand's accuracy, recommendation, and overall visibility in summaries and answers from ChatGPT, Gemini, Perplexity, Claude, and Google AI Overviews. A common challenge many brands face is measuring AI visibility's impact to justify investment.
Here's a use case to explain part of that challenge: A user asks ChatGPT to find the best cancer hospitals on the West Coast. In 69 of 71 ChatGPT answers, it recommends City of Hope, a cancer center in Los Angeles. A third-party AI visibility tracker says ChatGPT recommends City of Hope 97.81% of the time, but it ranked City of Hope first in only 25 of those 71 answers. Data shows that users overwhelmingly chose the first result or one of the top three in both traditional and AI-generated searches.
Here's how we define the following terms throughout this post: An appearance rate is the share of AI answers, across a fixed set of prompts run several times, that recommend the brand. The owned-domain citation rate is the share of answers that cite a page on the brand's own website.
How did public relations (PR) become a distribution channel for AI answers?
PR is a distribution channel for AI answers, in part, because ChatGPT, Claude, and Gemini cite earned media far more often than brand-owned content or paid ads and placements.
In a May 2026 study of AI citations, earned sources (journalism, academic research, government sites, encyclopedias, social platforms, and third-party company content) accounted for about 84% of citations. Owned and paid content together made up about 16%, paid and advertorial content 0.3%, and press releases 1.1%.
Journalism contributed to 27% of the links AI models cited in that study. The study found that 57% of journalism citations appeared within 12 months, so recent coverage carries more weight than an archive of older clips. The 5W's guide to earned media and AI search visibility covers how to earn that coverage.
The AI answer is often where the reader stops. As far back as March 2025, the Pew Research Center found that Google users who saw an AI summary clicked a traditional result on 8% of visits, compared to 15% when no summary appeared, and clicked a link inside the summary on about 1% of visits. These placements build awareness and increase branded searches later, which is why referral traffic can undercount PR's impact and muddy AI search attribution to business outcomes.
What can GEO measurement prove?
GEO measurement can show how often a brand appears across multiple prompt runs, provided the sample is large enough to distinguish one brand from another. In a January 2026 AI consistency study, the audience research company SparkToro and the AI tracking startup Gumshoe.ai had 600 volunteers run 12 recommendation prompts through ChatGPT, Claude, and Google's AI. They ran the prompts a combined 2,961 times in November and December 2025. The lists changed almost every time, yet some names kept returning: City of Hope appeared in 69 of 71 ChatGPT answers about West Coast cancer care hospitals.
Rand Fishkin, co-founder and CEO of SparkToro, started the project expecting AI tracking to be useless. Fishkin concluded that visibility percentage, measured across dozens to hundreds of prompts run several times each, is a reasonable metric.
GEO measurement can also show which sources models cite and if their answers about the brand are accurate. That turns "AI is talking about us" into a list of specific outlets, pages, and errors comms and marketing teams can act on.
What can't GEO measurement prove?
GEO measurement can't prove a brand's rank inside an AI answer, because the order of a recommendation list changes almost every time the question is asked. SparkToro found less than a 1 in 100 chance that ChatGPT or Google's AI returns the same list of brands twice. The odds of getting the same list in the same order were closer to 1 in 1,000. City of Hope, recommended in 69 of 71 ChatGPT answers, appeared first in only 25. Rand Fishkin wrote that any third-party software reporting a "ranking position in AI" is "full of baloney."
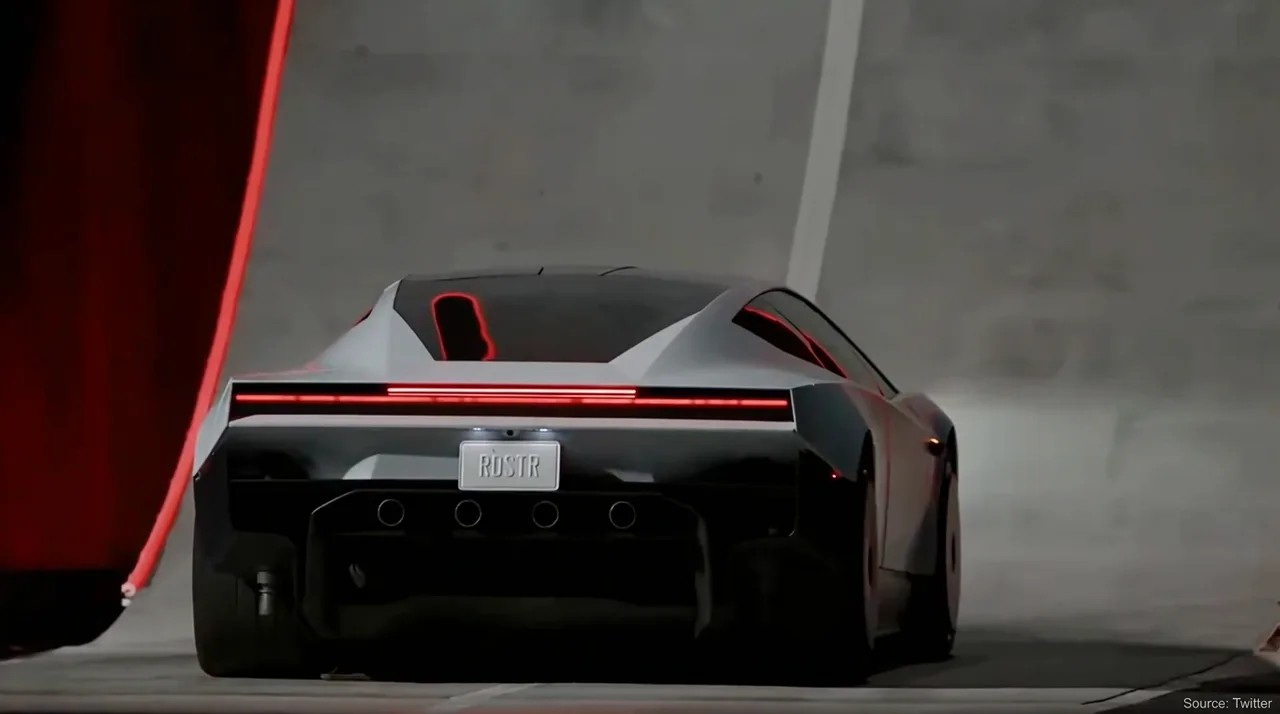
GEO measurement also doesn't separate overlapping brands. In 5W Research's Tesla Roadster flight-claims study, Tesla was identified in 40.7% of 216 scored answers. Its 95% confidence interval, 34.4% to 47.4%, overlapped those of Joby Aviation, PAL-V, Alef Aeronautics, and Archer Aviation. On that sample, the top five brands couldn't be ranked against each other.
One model's result doesn't substitute for the others. In the Tesla study, Vertical Aerospace appeared in 31.9% of Perplexity answers and 31.9% of ChatGPT answers, and in none of Gemini's. Citation data shows that ChatGPT, Claude, and Gemini share Wikipedia as a common source but otherwise cite largely different sets of domains.
The prompt set can support results before the model generates an answer. Eleven of the 24 prompts in 5W'study identified the Tesla Roadster, so part of Tesla's lead came from the questions themselves.
What did the Tesla Roadster news share about using PR and AI to improve model answers and media coverage?
5W October 2026 research discovered that AI models described the Tesla Roadster's flight and speed figures as claims, even when many day-one headlines didn't. The day after Tesla's October 15 unveiling, 5W asked Perplexity, ChatGPT, and Gemini 11 questions three times and scored 99 answers against a fact sheet. None of the models confirmed the Roadster as the world's first flying car.
The 0.81-second 0-to-60 mph time shows the gap between coverage and evidence. In 15 of 18 answers about that figure, the models disclosed that it hadn't been independently verified. Of 60 first-day press headlines, 41 used a flight word, and 19 of those answers had no hedge; 9 headlines quoted a 0-to-60 figure, and none of them were attributed to Tesla.
Tesla's website appeared in 23 of the 99 answers, second only to Wikipedia at 27, and the models still labeled the numbers as unproven. The models tied that caution to the absence of independent evidence. For a launch, the placement most likely to drive a favorable response in an AI answer is credible information accessible for fact-checking.
The study covers three models, queried through their APIs, with one reviewer scoring the answers against a written rubric.
How can brands measure AI visibility?
Brands can measure AI visibility as an appearance rate with a defined sample, a confidence interval, and a log of cited sources, and leave rank out of their reports. The table below shares what best practices can and can't support.
| Measure | What it can prove | What it can't prove |
|---|---|---|
| Appearance rate across repeated runs | How often models recommend the brand for a given question/prompt | Why the brand appears, or its position in the list |
| 95% confidence interval | Whether two brands' appearance rates differ beyond chance | Results for prompts outside the tested set |
| Cited-source log | Which outlets and pages the models pull answers from | That a cited page caused the mention |
| Accuracy score against a fact sheet | Whether answers state the brand's facts correctly at the time of the reporting | That the same answer will appear after a model update |
| Owned-domain citation rate | How often the brand's site is used as a source | Total brand mentions across the web |
| Rank or position in an answer | Very little, given list order changes almost every run | A stable standing against competitors |
The design determines if the numbers hold up. Research and identify the right prompts before testing; keep them neutral and unbranded, because buyers often ask about a category first. Run each prompt several times on relevant models and report each model's result separately. For example, using the studies in this post: SparkToro ran its prompts 60 to 100 times; the 5W study ran 24 prompts three times on each of four engines, for 288 runs.
Document and repeat runs of an identical prompt set before and after a campaign. A rise in citations and recommendations that clears the confidence interval, on the same prompts and models, is the closest brands can get to connecting coverage to an outcome.
For category benchmarks measured like this, refer to 5W's AI Visibility Index series.
Across multiple sources, PR's measurable result in AI search is frequency: how often models recommend a brand, the sources they cite, and their accuracy. A report that shares that data helps measurement; a report that states a rank doesn't. Because PR supplies most of the sources the models cite, both belong in a brand's AI measurement plan.