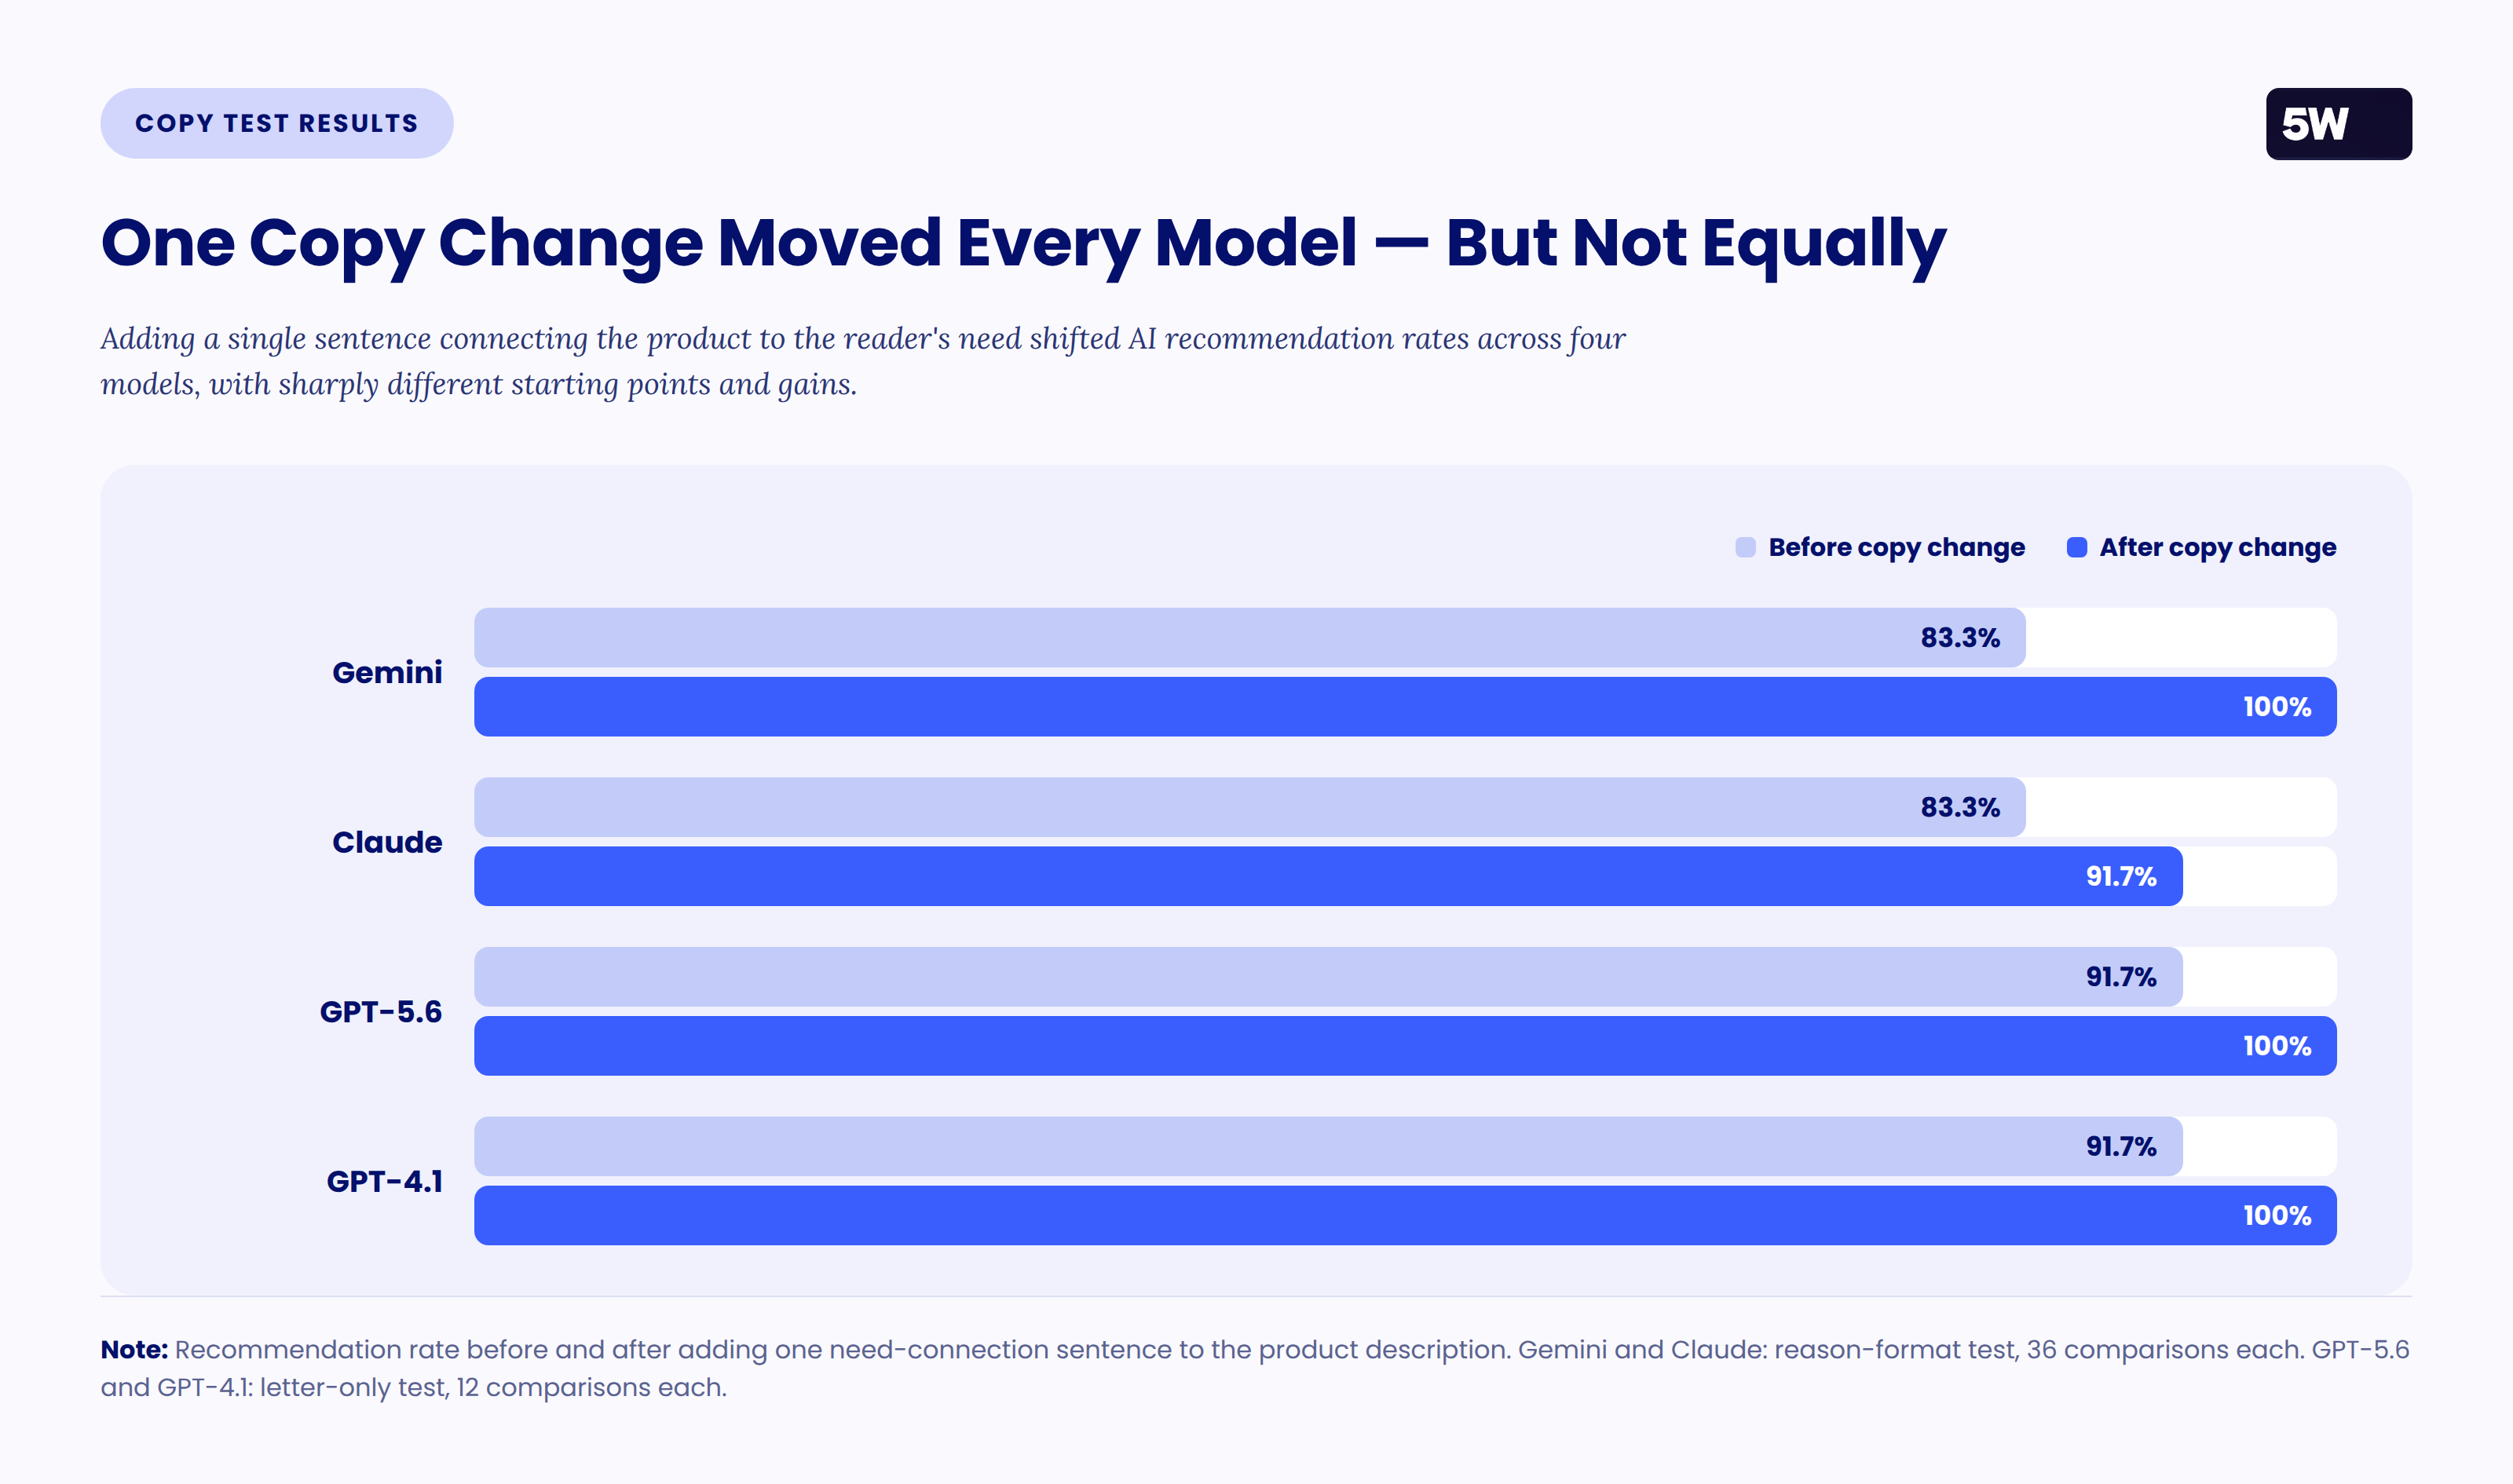
In a small test of one moisturizer, adding a sentence that connected the product to a stated need raised how often AI models picked it: Gemini from 83.3% to 100%, Claude from 83.3% to 91.7%, and GPT-5.6 and GPT-4.1 from 91.7% to 100%. Only Gemini's result was statistically significant, and all six of its switches happened when the product appeared second, so product position may explain the lift.
Last updated: October 28, 2026.
This is part of 5W's ongoing research into what increases AI-generated recommendations. In this dataset, the size of the increase depended on a brand's current visibility in a specific model and on the context surrounding the brand's product.
What Did the Copy Test Change?
The test changed one sentence in a product description. The first line stated the user's need, and the second line explained how the product met that need. All other lines, such as ingredients, were identical in both versions.
| Version | Copy used |
|---|---|
| Mention copy | "Sensitive skin in winter is a common seasonal skincare concern." |
| Connection copy | "This product is suitable for sensitive skin in winter." |
Which Competitors Were Tested?
The test compared a CeraVe-style moisturizer against six competitors in two sets, running each competitor twice, which gave 12 head-to-head comparisons in each data set.
- Two direct competitors: a fragrance-free moisturizer with ceramides, niacinamide, and glycerin, and another fragrance-free moisturizer with ceramides, hyaluronic acid, and amino acids.
- Four moderately competitive products: a fragrance-free water gel with hyaluronic acid and glycerin; a fragrance-free moisturizer with petrolatum, glycerin, and sorbitol; a gel cream with hyaluronic acid, peptides, and squalane; and a lightweight makeup priming lotion with glycerin, panthenol, and algae extract.
What Content Changes Were Worth Making?
The answer depends on the model and the test format. The table gives the raw numbers from the analysis, excluding averages. "Need mentioned" is the baseline copy and "Product connected to need" is the changed copy.
| Model and test | Need mentioned | Product connected to need | Recommendation results | Difference | p-value |
|---|---|---|---|---|---|
| Gemini 3.5 Flash, reason plus choice | 30/36 (83.3%) | 36/36 (100%) | 6/36 toward; 0 away | +16.7 pts | 0.03125 |
| Claude Sonnet 4.6, reason plus choice | 30/36 (83.3%) | 33/36 (91.7%) | 3/36 toward; 0 away | +8.4 pts | 0.25 |
| GPT-5.6, letter only | 11/12 (91.7%) | 12/12 (100%) | 1/12 toward; 0 away | +8.3 pts | 1.0 |
| GPT-4.1, letter only | 11/12 (91.7%) | 12/12 (100%) | 1/12 toward; 0 away | +8.3 pts | 1.0 |
The data are consistent with the idea that making the product-to-need relationship explicit can change AI recommendations, but the size and reliability of the effect depended on the model.
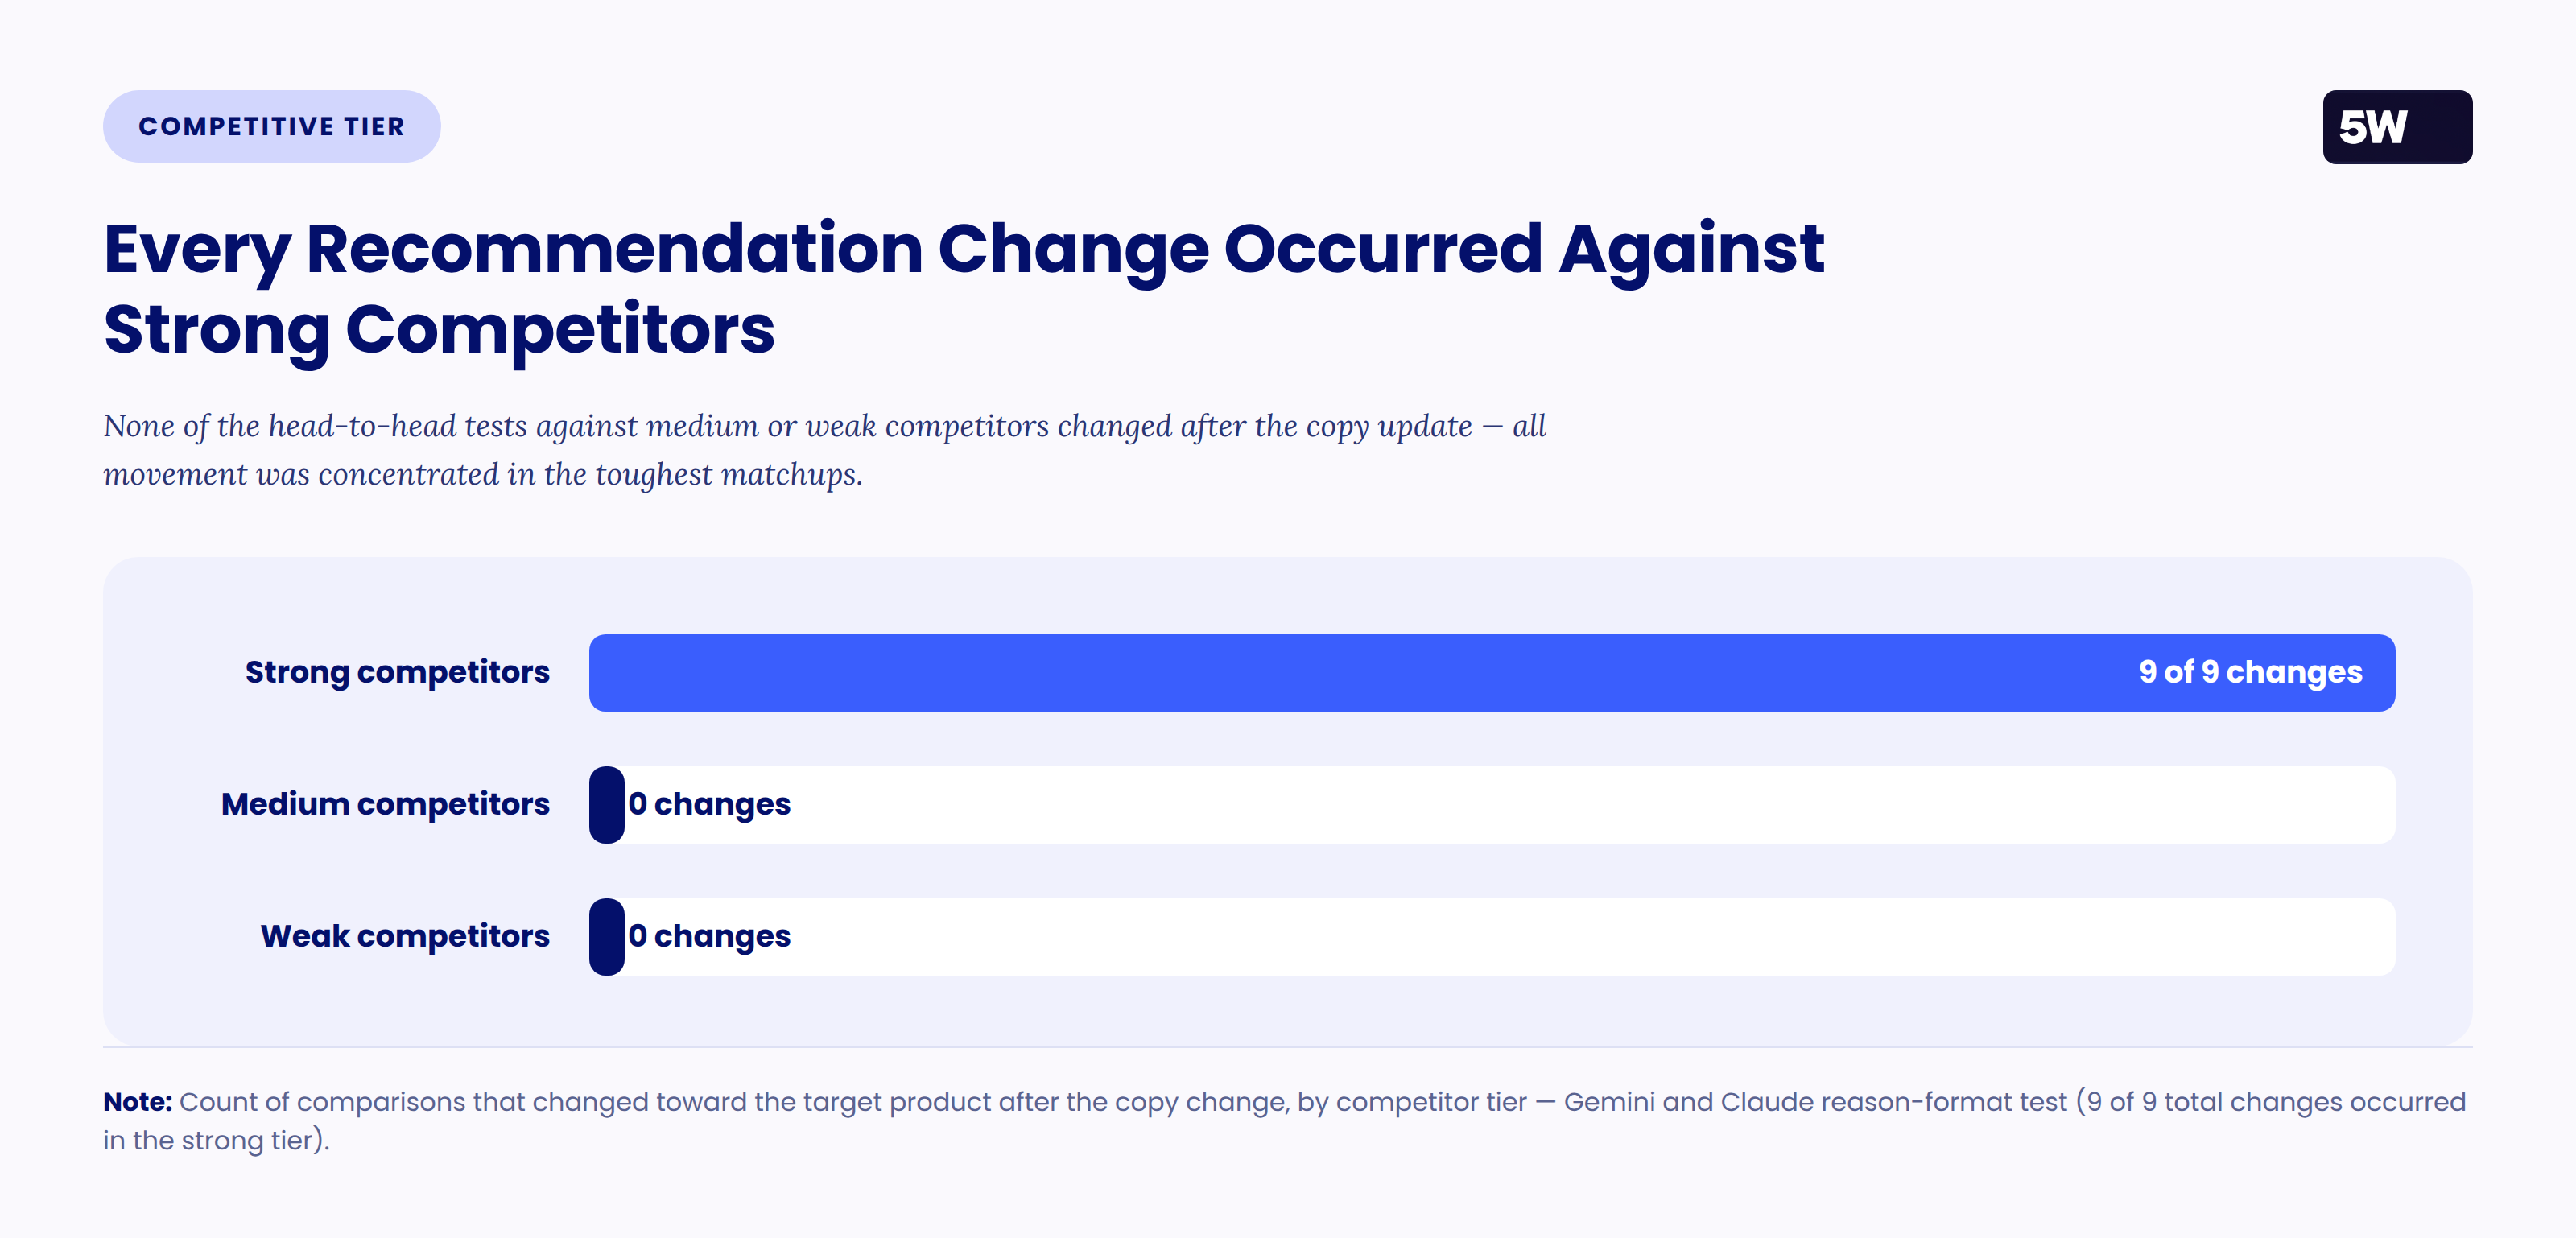
Most of the changed recommendations in Claude and Gemini came after the copy change and were against the strong competitor products. None of the recommendations changed in either comparison involving the medium or weak competitors.
When Is a Content Rewrite Likely to Have a Limited Return?
A content rewrite is likely to have a low return when the brand is already recommended in most relevant comparisons. GPT-5.6 and GPT-4.1 each selected the CeraVe-style moisturizer in 11 of 12 comparisons before the copy change, and after it every model selected the product in all 12.
Each of those models had one losing recommendation left to change. The new copy reversed that single loss, but the starting rate of 91.7% left little room to grow. 5W's research on why AI models skip new brands points the same way: changing a product description adds little when a model already has broad awareness of a product.
The ChatGPT runs reported only letters, so the test cannot show which product characteristics (cream, ceramides, hyaluronic acid, glycerin, fragrance-free) drove the original 11 selections.
Why Can't the Gemini Lift Be Credited to the Copy Alone?
The Gemini lift cannot be credited to the copy alone because every one of its six switches happened when the CeraVe-style product was listed second. Before the connection sentence, Gemini chose the product 18 of 18 times when it appeared first and 12 of 18 times when it appeared second. Afterward, it chose the product 18 of 18 times in both positions.
Product rank, not only the copy change, therefore appears to have been at least partly responsible, and another test would be needed to separate the two effects.
How Did the Answer Format Change the Results?
The answer format changed the starting rate and, for Claude, the direction of the measured effect, as the table shows.
| Evaluation | Result | Implication |
|---|---|---|
| How did the model answer? | Gemini's baseline was 58.3% in the letter-only test and 83.3% in the reason-format test. Claude moved from 66.7% to 50% in the letter-only test, but from 83.3% to 91.7% when it gave a reason. | Answer instructions changed the starting rate and, for Claude, the direction of the effect. |
| What counted as success? | Success meant selecting the CeraVe-style product. The study did not measure citations or brand mentions. | A recommendation, a citation, and a mention are different outcomes and should not be merged into one score. |
| Was product order controlled? | Gemini chose the product 18/18 times when it appeared first and 12/18 when second before the change, and 18/18 in both positions after. | The 16.7-point lift cannot be attributed to copy alone without another test. |
What Should a Pilot Show Before a Brand Scales an AI Search Program?
A pilot should tie a specific content change to a specific improvement in an AI outcome that matters to the brand. The evidence supports a staged approach: establish a model-level baseline, identify priority recommendations, make small controlled changes, run multiple comparisons, and scale only if the improvement is consistent.
Before a large Generative Engine Optimization (GEO) or content rewrite, a brand should baseline its current recommendations and gaps, then test small copy changes against competitors on relevant broad prompts. A site-wide rewrite without that evidence may create expense with limited potential for improvement. 5W's GEO optimization practice covers the measurement side of this work.
For how models categorize beauty brands, see how LLMs categorize beauty brands. For which brands AI cites most, see the Beauty AI Visibility Index 2026, and for the communications side, see 5W's consumer beauty PR practice.
What Are the Limitations of This Test?
The test has eight limitations, and they weaken any general claim that connecting a product to a need raises AI recommendations.
- Position bias is confirmed for Gemini. Each of Gemini's six switches toward the target happened in a second-position cell, where the position gap had suppressed the target pick (66.7% to 100%). The data cannot separate a copy effect from a rank effect.
- Claude moved in opposite directions across tests. In the letter-only test Claude fell from 66.7% to 50% (3 away, 1 toward, net negative). In the reason-format test it rose from 83.3% to 91.7% (3 toward, 0 away). The models and copy variants were the same.
- Models disagree on which cells change. In the reason-format test, Gemini and Claude share one flip cell out of twelve, and Gemini's other flip is unique to it. In the letter-only test, no cell flipped toward the target more than once. This makes model-specific noise more likely than a general mechanism.
- The reasoning-text mechanism does not support itself. Gemini mentioned the need in its own stated reasoning less often after the change (18/36 to 15/36), the opposite of what "the model is now reasoning about the need" would predict. Claude's mentions rose (6/36 to 10/36). The two models disagree on the metric meant to explain the effect.
- The significant result is small and concentrated. Gemini's p-value of 0.03125 rests on 6 discordant trials that fell within two unique combinations of cell and position, each rerun three times, not six independent cells. The GPT-5.6 and GPT-4.1 effects are single flipped rows (p = 1.0) and were never rerun.
- Two models could not be tested as specified. ChatGPT's original run failed (0 of 24 valid) before a temperature-field fix, and Perplexity's 24 rows were all errors and were never rerun, so no clean condition data exists for it.
- Baseline visibility depends on answer format. Gemini's baseline was 58.3% in the letter-only test and 83.3% in the reason-format test.
- The scope is narrow. All data came from one category (moisturizers), a fixed set of six competitors, and one pair of copy variants. The results should not be read as general findings about "content changes."
How Was the Test Run?
The study used two test formats, and the headline figures come from different ones, so they are not equivalent designs.
- Letter-only test: Gemini, Claude, GPT-5.6, GPT-4.1, and Perplexity were each told to answer with a single letter (A or B) for 12 head-to-head cells (2 direct or strong competitors and 4 moderate competitors, each with two copy conditions). No reasoning was captured. The run used 96 rows, plus a 48-row re-run for ChatGPT. GPT-5.6 and GPT-4.1 each had 23 of 24 valid target picks (11/12 for the baseline copy and 12/12 for the connection copy).
- Reason-format test: Gemini and Claude each gave a short reason and a product code, with 3 repetitions per cell and condition, at both product positions (first and second). The run used 144 rows. Gemini went from 83.3% to 100% and Claude from 83.3% to 91.7%.
The Gemini and Claude figures come from the reason-format test and the GPT figures from the letter-only test, which differ in prompt structure, number of trials, and repetitions (three per cell for Gemini and Claude, one for the GPT models). Gemini's position breakdown under the baseline copy was 100% with the target first and 66.7% with the target second, and 100% in both positions under the connection copy. Claude's was 83.3% in both positions under the baseline copy, and 83.3% first and 100% second under the connection copy. Raw data files are available on request.
For the concern-by-concern view, see the Skincare AI Visibility Index 2026 and its reports on acne, anti-aging and retinoids, hyperpigmentation and brightening, sensitive skin and barrier repair, and SPF and sun protection.
Frequently Asked Questions
Does adding a product-to-need sentence increase AI recommendations?
In this test it raised recommendation rates for every model, but the evidence is weak. Only Gemini's result was statistically significant (p = 0.03125), and all six of its switches occurred when the product appeared second, so position may explain the lift.
Which models were tested?
The reason-format test used Gemini and Claude, and the letter-only test used GPT-5.6 and GPT-4.1, with Gemini, Claude, and Perplexity also included in its design. Perplexity's runs all returned errors and were never rerun.
When is rewriting product copy unlikely to help?
Rewriting is unlikely to help when the product is already recommended in most comparisons. GPT-5.6 and GPT-4.1 already picked the CeraVe-style moisturizer in 11 of 12 comparisons before the change, leaving one loss to reverse.
Why were the results different between Gemini and Claude?
The two models disagreed on which cells changed and moved in different directions depending on the test format. Claude fell from 66.7% to 50% in the letter-only test and rose from 83.3% to 91.7% in the reason-format test.
What should a brand do before investing in an AI search program?
A brand should baseline its current recommendations by model, make small controlled copy changes, run multiple comparisons, and scale only when the improvement is consistent.
Can these results be applied to other product categories?
No. All data came from one category (moisturizers), six competitors, and one pair of copy variants, so the results should not be read as general findings about content changes.